Tag Archives: Data Management

The AI Capability Gap: Why Businesses Aren’t Realizing AI’s Full Potential

AI Capability Gap

Businesses have access to AI systems that can summarize documents, analyze data, write code, research topics, and coordinate tasks. Yet many organizations still use these tools primarily to answer questions or draft emails. The technology is advancing rapidly, but the way it is incorporated into everyday work changes much more slowly.

The gap between available AI capabilities and their practical use is often described as capability overhang. This disconnect reflects more than technological limitations. Employee familiarity, organizational processes, and the ability to integrate advanced AI tools into existing workflows all influence how effectively businesses adopt the technology. The business question is not simply what AI can do, but how effectively organizations put it to work.

AI Capabilities Are Improving Faster Than Business Workflows

AI performance is difficult to summarize with a single number because systems vary across reasoning, coding, retrieval, and tool use. One useful measure comes from METR, which studies the length of software-related tasks that AI agents can complete. Its March 2025 analysis estimated that the task-completion time horizon of leading systems had roughly doubled every seven months over the period studied.

A time horizon does not mean an AI agent can reliably operate for that many minutes without supervision. It refers to the estimated duration a human expert would need to complete tasks at a specified model success rate. METR also identifies limitations involving task selection and how well its results generalize to real work. Even so, the research illustrates why the scope of potential AI assistance is expanding.

Business processes do not automatically adjust when model capabilities improve. Existing applications, approval requirements, employee responsibilities, data access, and habits can remain unchanged. A model may become better at a task while the organization continues to handle that task through the same manual sequence.

Understanding the AI Capability Gap

The capability gap appears when access to powerful tools outpaces practical understanding and implementation. An employee may know that an AI assistant can write text but not realize it can analyze a spreadsheet, compare technical documents, or organize research steps. Another employee may know these features but lack access to the data needed to use them at work.

OpenAI’s January 2026 report, Ending the Capability Overhang, describes differences in how people use advanced AI features. Among subscribers on the same Plus plan, it reports that users at the 95th percentile consumed approximately seven times more thinking capability than median users. This is a usage comparison, not evidence that power users are seven times more productive.

The report also identifies differences in advanced usage across countries. These findings illustrate uneven adoption, but they do not establish that every organization can obtain the same results by increasing model usage. More intensive interaction may reflect different tasks, skills, incentives, and work environments.

For businesses, the distinction is between access and effective application. Providing subscriptions removes one barrier. It does not establish which processes deserve attention, what successful output looks like, or who is responsible when AI makes a mistake.

Why Businesses Struggle to Capture AI Value
AI Workflow

Employees Stay With Familiar Uses

Question answering and drafting are straightforward places to begin. They fit existing routines and require little process change. Advanced work often involves choosing tools, preparing inputs, checking outputs, and connecting systems. That effort can make employees return to simpler applications even when better options exist.

AI can also be counterintuitive. Employees may not know an unfamiliar task is possible until someone demonstrates it using relevant data. Generic prompt training may increase familiarity without teaching people to recognize opportunities in their responsibilities.

Information and Systems Remain Disconnected

A useful business workflow may depend on information from customer records, project documentation, financial systems, and employee communications. If those sources are inconsistent or inaccessible, a capable model has little reliable context.

Consider a hypothetical service company preparing customer renewal proposals. Staff review earlier contracts, gather project updates, verify pricing, and summarize account history. AI could organize approved information into a draft, while integrations retrieve current records and flag missing details. An account manager would check conflicting records and verify commercial terms before sending it. The improvement comes from streamlining the full renewal process, not just drafting faster.

Organizations Automate Activities Instead of Outcomes

Generating more reports or customer messages is easy to measure. Demonstrating that those outputs improved a decision or completed a process is harder. A company might celebrate thousands of AI-assisted interactions while employees spend additional time correcting them.

Google’s 2025 DORA research on AI-assisted software development found that AI tends to amplify existing organizational strengths and weaknesses. The report focuses on software delivery rather than every industry, but its lesson is relevant: better tools are not substitutes for healthy processes, clear responsibilities, and coordinated teams.

From Individual Prompts to Repeatable Workflows

Move beyond isolated prompts by starting with a business result, such as an accurate customer briefing or faster reconciliation. Map the sequence of tasks, information sources, handoffs, and decisions needed to complete the work. Identify where AI can assist and where existing applications or employees must take over.

For customer support, an employee might search account history and policy documents, draft a reply, and record the interaction. AI could retrieve approved material and prepare a response, while the workflow defines escalation and record-update permissions.

A workflow is more than a series of AI-generated sentences. It requires reliable inputs, predictable handoffs, and confirmation that the correct work was completed. AI agents and integrations can support multistep tasks, but their permissions and exception handling should match the risks.

Not every organization needs sophisticated autonomous systems. For some teams, an approved knowledge source and a human reviewer offer more dependable value than a complex agent. The right level of automation depends on process requirements and consequences of errors.

Closing the Gap Through Training and Workflow Design
AI Training

Teach Capabilities Through Real Tasks

Begin with a limited pilot of a recurring process and train employees using realistic materials. Show them how to evaluate AI output, recognize missing context, and return uncertain work to a person. Assign a pilot owner, gather feedback from participants, and use the results to improve the training before extending the approach to other teams.

An exercise might compare three approaches to preparing a project update: manual consolidation, AI-assisted drafting from approved notes, and an integrated process that collects information automatically. Employees can see where effort shifts and which safeguards remain necessary.

Build Around Trusted Data and Clear Ownership

Before connecting AI to business systems, determine which sources contain authoritative information and who may access them. Establish rules for data handling, approval, and error correction. A summary that contradicts the system of record should not silently become an official record.

Software integration can move approved information between applications, but the connection itself is not proof of reliability. Teams must validate inputs, control permissions, log consequential actions, and define recovery from mistakes. These foundations matter when expanding AI from content assistance into operations.

Make Effective Uses Reusable

Make successful workflows discoverable and reusable. Record their purpose, required inputs, limitations, review standards, and expected results. Share practical demonstrations, examples, and employee feedback so effective use spreads beyond the original pilot.

Ownership matters after launch. As models, business rules, and source systems change, processes require maintenance. Assign someone to evaluate performance, respond to exceptions, and decide when a workflow should be revised or retired.

Measure Business Impact, Not AI Activity

A practical pilot needs a baseline. Measure the current process before introducing AI, including completion time, rework, errors, and employee effort. Then compare the AI-assisted approach on similar work, accounting for time spent checking outputs and correcting mistakes.

Measures should reflect the objective. A sales team might track qualified opportunities rather than messages sent. A software team might track tested changes delivered rather than code generated. An operations team might compare resolved cases and exception rates rather than automated actions.

Results require context. A faster process that increases customer complaints or exposes sensitive data is not necessarily an improvement. Evaluate cost, reliability, adoption, and consequences of failure before expanding. Successful scaling depends on whether the process works outside a supervised trial.

Final Thoughts

Closing the AI Capability Gap requires more than access to advanced technology. Businesses need employees who understand how to apply AI, reliable information to support those applications, and workflows designed around meaningful outcomes.

As AI capabilities continue to advance, the advantage will not necessarily belong to organizations using the most sophisticated tools. It will belong to those that can consistently translate available capabilities into reliable improvements in how work gets done.
Data Dynamo: Unveiling the Supreme Database Titans of 2024

Database ERD

Navigating the labyrinth of technological advancement, particularly in the domain of databases, is not only pertinent but also profoundly engaging. As we step into the throes of 2024, the digital infrastructure of businesses is revolutionized by an array of databases, each a juggernaut in its own right. In this cosmos of data storage and retrieval, uncovering the top database technologies is crucial for tech executives and enthusiasts alike. Within this ensemble of digital titans, several database technologies rise to prominence as the pillars of data management. In this blog we meticulously compare and contrast the premier databases of the year to discern their unique strengths and areas of application. 

MySQL:

MySQL remains a top choice for reliability and cost-effectiveness, known for its ease of deployment and management. Its steadfast commitment to ACID (atomicity, consistency, isolation, and durability) principles ensures the highest level of reliability, essential for modern enterprises.  MySQL’s extensive community support and compatibility with various operating systems make it an ideal solution for businesses of all sizes.

MySQL Database

Beyond these fundamentals, MySQL offers an array of fast-loading utilities accompanied by various memory caches, streamlining the maintenance and administration of servers. Its compatibility with an extensive list of programming languages, with a notable synergy with PHP, means that it can slide seamlessly into almost any technology stack. Moreover, performance is a front-runner, as MySQL delivers high-speed results without having to sacrifice any of its core functionalities.

MySQL, offered by Oracle, provides a balance between cost efficiency and performance. Pricing ranges from $2,140 to $6,420 for 1-4 socket servers and $4,280 to $12,840 for setups over five sockets. Its open-source nature under the GNU GPL enables free usage and customization. Explore MySQL at https://www.mysql.com/.

PostgreSQL:

PostgreSQL ensures Data Integrity with Primary Keys, Foreign Keys, Explicit Locks, Advisory Locks, and Exclusion Constraints. These features orchestrate data access, ensuring transaction consistency and fortifying the database’s resilience against anomalies. PostgreSQL excels in SQL features with Multi-Version Concurrency Control (MVCC) for high throughput. It handles complex SQL queries, including full support for SQL Sub-selects, appealing to SQL aficionados. Streaming Replication ensures high availability and disaster recovery.

Postgre SQL

In stark contrast to many other database technologies, PostgreSQL stands as an emblem of community-driven innovation, provided free of charge. This enterprise-grade database system, while lacking a traditional price tag, does not skimp on capabilities, owing to its development and continued refinement to a dedicated cohort of volunteers and backing enterprises. It prides itself on complete freedom of use under the liberal open-source PostgreSQL License. To peek into the extensive world of PostgreSQL or to become part of its vibrant community, head over to https://www.postgresql.org/.

Microsoft SQL Server:

Microsoft SQL Server stands not just as a pillar in the realm of traditional RDBMS (Relational Database Management System Software) but also as an architect of the ever-expanding Big Data landscape. Harnessing its prowess, organizations can construct their elite Data Lakes, serving as grand repositories that amalgamate disparate data, structured or not, into a cohesive pool. This confluence of data empowers users to embark on insightful expeditions across their entire datasets, directly querying the vast lakes without the onerous need to move or replicate precious data.

In the name of security—a paramount concern in today’s data-driven universe—Microsoft SQL Server brings its A-game with cutting-edge tools for data classification, protection, and monitoring. It stands vigilant, constantly scanning for anomalies, and is a fortifying digital fortress with timely alerts on any suspicious activities, security gaps, or configuration errors.

SQL Database

Microsoft SQL Server’s graphical tool empowers users to design, create tables, and explore data without intricate syntax. It seamlessly integrates data from various sources via an extensive connector library. With new transformations in the SQL Server Analysis Services (SSAS) Tabular Model, users gain advanced capabilities to manipulate and combine data.

Microsoft SQL Server offers diverse editions to suit various enterprise needs. The Enterprise edition is priced at $15,123, while the Standard edition offers options like per-core pricing ($3,945), server pricing ($989), and CAL option ($230). Volume licensing and hosting channels further influence pricing. Learn more at https://www.microsoft.com/en-us/sql-server/sql-server-2022-pricing.

MongoDB:

MongoDB’s architecture ensures that scaling to meet the demands of growing data is never an impediment. Thanks to its intrinsic scalability, it can flaunt clusters that burgeon past the hundred-node mark effortlessly, managing millions of documents without breaking a sweat. Its widespread adoption across a myriad of industries is a testament to MongoDB’s capability to handle expansive and intricate datasets. MongoDB ensures high availability through replica sets, guaranteeing uninterrupted service and data durability. In cases of hardware failure, it redistributes load across servers or duplicates data to maintain operational integrity, ensuring a seamless user experience.

Mongo DB

MongoDB, a prominent figure in the NoSQL landscape, provides a free entry point through MongoDB Atlas’s perpetual free tier. Celebrated for scalability and developer-friendliness, MongoDB remains a strong player in data management. Discover more at https://www.mongodb.com/pricing.

Oracle: 

Oracle’s resilience and data recovery features are vital for uninterrupted business operations. Real Application Clusters (RAC) ensure high availability by enabling multiple instances on different servers to access a single database. This fault-tolerant and scalable setup underscores Oracle’s commitment to continuous operation, even during server failures. 

Oracle’s service offerings cater to a wide array of demands, providing precise solutions for diverse business requirements. Starting with the Oracle Database Standard Edition, which offers essential features for typical workloads, users can scale up to the Enterprise Edition for more comprehensive capabilities. Additionally, Oracle provides specialized tiers such as the High Performance and Extreme Performance editions, designed to meet the demands of high-throughput and mission-critical environments. 

Oracle DB

Each tier is carefully crafted to deliver optimal performance and reliability, ensuring that businesses can effectively manage their data infrastructure. Furthermore, Oracle’s pricing structure accommodates varying usage scenarios, with options for flexible scaling based on virtual CPU (vCPU) usage. To review Oracles pricing structure click here. 

Remote Dictionary Server (Redis):

Redis shines in caching and in-memory data handling, offering unparalleled speed and versatility. Supporting various data structures like strings, lists, hashes, bitmaps, HyperLogLogs, and sets, Redis caters to the diverse needs of modern applications. Moreover, Redis seamlessly integrates with popular programming languages like Java, Python, PHP, C, C++, and C#, ensuring compatibility across different development environments and accelerating data-intensive operations.

Redis

Redis offers a dynamic ecosystem where free open-source frameworks coexist with commercial variants. While the community version is free, enterprise solutions like Redis Enterprise, with enhanced features and support, operate on a subscription model. Explore Redis offerings on their website.

Elasticsearch:

Elasticsearch represents the epitome of scalability seamlessly embraced in its design. Out-of-the-box distributed systems are the backbone of its architecture, enabling data to be reliably shared across multiple servers and nodes, hence bolstering higher availability and resilience in the face of demanding workloads.  This design decision is not just a matter of capability; it represents a promise of reliability, ensuring that as data volumes escalate, Elasticsearch stands prepared to accommodate the surge seamlessly. 

Elasticsearch, a prominent member of the NoSQL ecosystem, adopts a dual licensing model, offering users the choice between the Server Side Public License (SSPL) or the Elastic License. This flexibility allows organizations to select the licensing option that best fits their needs and compliance requirements. In addition to its licensing options, Elasticsearch introduces a unique billing system based on Elastic Consumption Units (ECUs), which aligns usage with expenditure. This innovative approach enables organizations to scale their Elasticsearch deployments elastically according to their requirements, without being bound by traditional fixed licensing models. To review Elasticseach’s pricing structure click here .

Oracle DB

Cassandra:

Cassandra excels in fine-tuning consistency levels for data operations, allowing developers to balance performance and accuracy. Its column-family data model adeptly handles semi-structured data, providing structure without compromising schema flexibility. With the Cassandra Query Language (CQL), which resembles SQL, transitioning from traditional databases is simplified. This, coupled with standard APIs, positions Cassandra as a scalable, reliable, and user-friendly database choice, lowering adoption barriers for tech teams.

Apache Cassandra, rapidly rising in the NoSQL landscape, is renowned for its free and open-source nature. For enterprise-grade support and features, commercial vendors offer options. Amazon Keyspaces (for Apache Cassandra) provides decentralized storage, billing $1.45 per million write request units and $0.29 per million read request units. Explore more at https://cassandra.apache.org/_/index.html.

MariaDB:

MariaDB stands out with advanced features like microsecond precision, crucial for time-sensitive applications, table elimination for optimized query processing, scalar subqueries for enhanced functionality, and parallel replication for faster database synchronization and analytics. Its compatibility with major cloud providers simplifies deployment and management in cloud infrastructures. MariaDB supports various storage engines, including Aria for crash safety, MyRocks for efficiency, and Spider for sharing across servers, offering flexibility and functionality for diverse data types and use cases.

MariaDB is a forerunner in the open-source database community maintaining  its allegiance to cost-effectiveness and robust efficiency. Ideal for newcomers to the AWS ecosystem, the Amazon RDS for MariaDB invites users with its introductory Free Tier – inclusive of substantive resources to pilot their database endeavors. For details on how to harness this SQL-driven database for your transformative projects, consult MariaDB’s central hub.

Database Total

IBM DB2:

DB2 is a trusted enterprise data server, facilitating seamless deployment across on-premises data centers and public/private clouds. Its flexibility enables organizations to adopt hybrid data management approaches aligned with operational needs and strategic goals. DB2 excels in data compression, featuring adaptive compression, value compression, and archive compression, significantly reducing storage footprints and costs. Administrative tasks are simplified with DB2’s self-tuning and self-optimizing features, driven by machine learning. This ensures optimal database performance with minimal intervention, reducing time and effort for routine maintenance and tuning.

IBM

IBM’s offering in the data management framework, DB2, acquaints users with its prowess through a complimentary trial on the IBM Cloud. This gesture extends to a no-strings-attached experience, with an available upgrade to a paid tier at USD 99 per month, comprehensive of full functionality and sweetened by USD 500 in credits. Questers of this high-caliber database solution can embark on their journey by navigating to  https://www.ibm.com/products/db2/pricing.

SQLite:

SQLite’s appeal lies in its simplicity and ease of use. It operates without a separate server process, complex installation, or administration. A complete SQL database is stored in a single cross-platform disk file, requiring no configuration, making it highly portable and ideal for simplicity-focused scenarios. Additionally, SQLite adheres broadly to SQL standards, supporting commands like SELECT, INSERT, UPDATE, and DELETE, making it familiar to developers accustomed to other SQL databases. Being in the public domain, SQLite can be freely used and distributed without any restrictions, fees, or royalties.

SQLite, remaining loyal to the public domain, provides all-inclusive accessibility to its database solutions, with no fees levied for any usage. As the quintessence of an easily embeddable, lightweight relational database engine, SQLite is the go-to for myriad applications across the globe, with Microsoft not just embracing, but actively integrating it. Encounter SQLite in its purest form at its principal domain: SQLite.

Data Lake

Amazon DynamoDB:

DynamoDB provides consistent single-digit millisecond response times for large-scale applications. Its architecture allows seamless, on-demand scaling without manual intervention, ensuring performance under varying demands. Multi-AZ deployments ensure high availability and fault tolerance, with fast failovers and data replication across three Availability Zones for accessibility and security. Native support for document and key-value data models optimizes performance for distinct access patterns, enhancing efficiency.

Amazon DynamoDB offers an attractive free tier with 25 GB of storage and 25 units each of Write and Read Capacity, sufficient for managing 200 million monthly requests. Its On-Demand billing charges $1.25 per million write request units and $0.25 per million read request units, allowing flexibility to scale with demand. Learn more from Amazon’s DynamoDB guide. To review Amazon DynamoDB’s pricing structure click https://aws.amazon.com/dynamodb/pricing/.

In Conclusion

While relational databases continue to shoulder the bulk of transactional workloads, NoSQL databases have adeptly found their place in handling the complexities of semi-structured and unstructured data. The choice of database, as always, is contingent on the specific needs and nuances of individual businesses. As we continue to delve into the big data era, it is not just the deployment of databases that is vital but also the synthesis of these technologies with wider business strategies.

AIoT: How the Intersection of AI and IoT Will Drive Innovation for Decades to Come

We have covered the evolution of the Internet of Things (IoT) and Artificial Intelligence (AI) over the years as they have gained prominence. IoT devices collect a massive amount of data. Cisco projects by the end of 2021, IoT devices will collect over 800 zettabytes of data per year. Meanwhile, AI algorithms can parse through big data and teach themselves to analyze and identify patterns to make predictions. Both technologies enable a seemingly endless amount of applications retained a massive impact on many industry verticals.

What happens when you merge them? The result is aptly named the AIoT (Artificial Intelligence of Things) and it will take IoT devices to the next level.

WHAT IS AIOT?

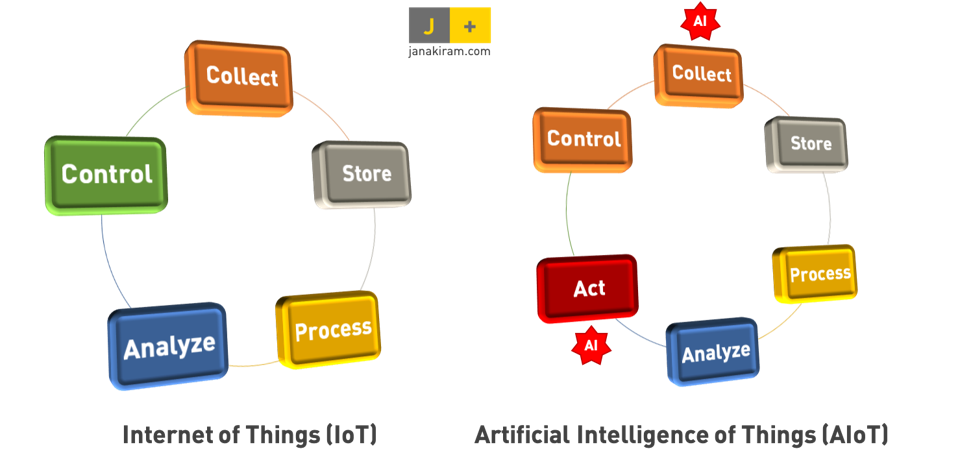
AIoT is any system that integrates AI technologies with IoT infrastructure, enhancing efficiency, human-machine interactions, data management and analytics.

IoT enables devices to collect, store, and analyze big data. Device operators and field engineers typically control devices. AI enhances IoT’s existing systems, enabling them to take the next step to determine and take the appropriate action based on the analysis of the data.

By embedding AI into infrastructure components, including programs, chipsets, and edge computing, AIoT enables intelligent, connected systems to learn, self-correct and self-diagnose potential issues.

960x0

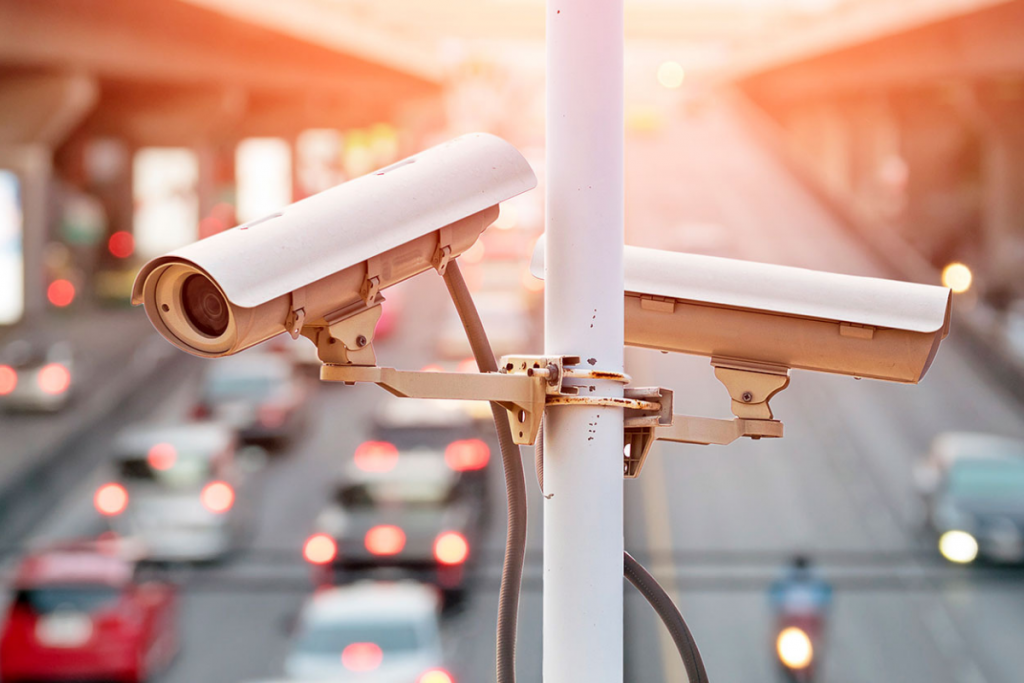
One common example comes in the surveillance field. Surveillance camera can be used as an image sensor, sending every frame to an IoT system which analyzes the feed for certain objects. AI can analyze the frame and only send frames when it detects a specific object—significantly speeding up the process while reducing the amount of data generated since irrelevant frames are excluded.

CCTV-Traffic-Monitoring-1024x683

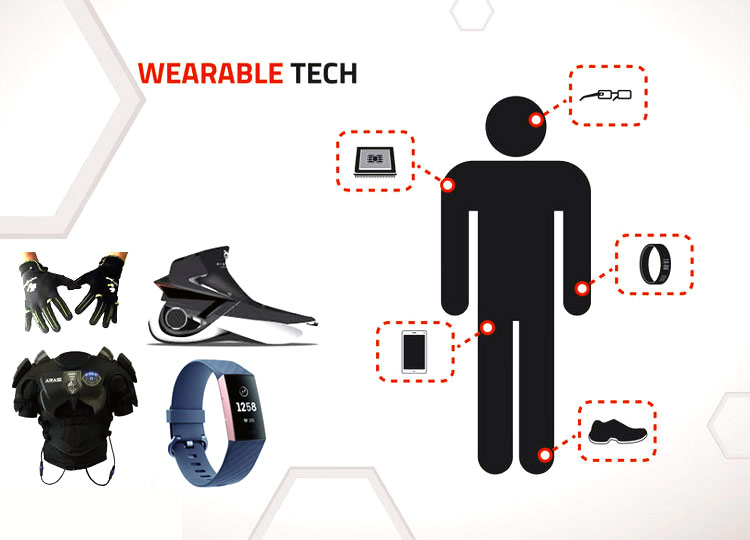
While AIoT will no doubt find a variety of applications across industries, the three segments we expect to see the most impact on are wearables, smart cities, and retail.

WEARABLES

Wearable-IoT-Devices

The global wearable device market is estimated to hit more than $87 billion by 2022. AI applications on wearable devices such as smartwatches pose a number of potential applications, particularly in the healthtech sector.

Researchers in Taiwan have been studying the potential for an AIoT wearable system for electrocardiogram (ECG) analysis and cardiac disease detection. The system would integrate a wearable IoT-based system with an AI platform for cardiac disease detection. The wearable collects real-time health data and stores it in a cloud where an AI algorithm detects disease with an average of 94% accuracy. Currently, Apple Watch Series 4 or later includes an ECG app which captures symptoms of irregular, rapid or skipped heartbeats.

Although this device is still in development, we expect to see more coming out of the wearables segment as 5G enables more robust cloud-based processing power, taking the pressure off the devices themselves.

SMART CITIES

We’ve previously explored the future of smart cities in our blog series A Smarter World. With cities eager to invest in improving public safety, transport, and energy efficiency, AIoT will drive innovation in the smart city space.

There are a number of potential applications for AIoT in smart cities. AIoT’s ability to analyze data and act opens up a number of possibilities for optimizing energy consumption for IoT systems. Smart streetlights and energy grids can analyze data to reduce wasted energy without inconveniencing citizens.

Some smart cities have already adopted AIoT applications in the transportation space. New Delhi, which boasts some of the worst traffic in the world, features an Intelligent Transport Management System (ITMS) which makes real-time dynamic decisions on traffic flows to accelerate traffic.

RETAIL

AIoT has the potential to enhance the retail shopping experience with digital augmentation. The same smart cameras we referenced earlier are being used to detect shoplifters. Walmart recently confirmed it has installed smart security cameras in over 1,000 stores.

smart-shopping-cart

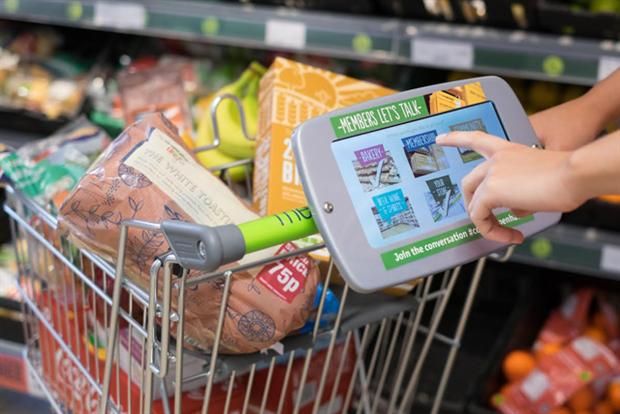
One of the big innovations for AIoT involves smart shopping carts. Grocery stores in both Canada and the United States are experimenting with high-tech shopping carts, including one from Caper which uses image recognition and built-in sensors to determine what a person puts into the shopping cart.

The potential for smart shopping carts is vast—these carts will be able to inform customers of deals and promotion, recommend products based on their buying decisions, enable them to view an itemized list of their current purchases, and incorporate indoor navigation to lead them to their desired items.

A smart shopping cart company called IMAGR recently raised $14 million in a pre-Series A funding round, pointing toward a bright future for smart shopping carts.

CONCLUSION

AIoT represents the intersection of AI, IoT, 5G, and big data. 5G enables the cloud processing power for IoT devices to employ AI algorithms to analyze big data to determine and enact action items. These technologies are all relatively young, and as they continue to grow, they will empower innovators to build a smarter future for our world.