Category Archives: Software Development

Integrating AI Agents with Enterprise Software: MCP, RAG, CRM, and ERP Systems

AI Integrations

An AI agent becomes operationally useful when it can work with the information and systems a business already relies on. A model may interpret a request and propose a next step, but resolving a service case, updating a customer record, or checking a purchase order requires dependable connections to enterprise applications. The central engineering challenge is not simply giving an agent access. It is controlling what information it sees, what actions it may take, and how failures are handled.

Four concepts frequently appear in these designs: APIs for connecting applications, Model Context Protocol (MCP) for exposing tools and resources to AI applications, retrieval-augmented generation (RAG) for grounding answers in organizational knowledge, and integrations with systems of record such as CRM and ERP platforms. They serve different purposes and are often used together.

Start with the Systems of Record

Customer relationship management (CRM) software stores account details, service cases, sales activity, and customer interactions. Enterprise resource planning (ERP) systems manage operational processes such as purchasing, inventory, finance, and fulfillment. An agent assisting either function must distinguish authoritative records from unverified notes and generated summaries.

Consider a business responding to a shipment dispute. The customer-service platform contains the conversation, the CRM identifies the account, and the ERP or order-management system records fulfillment status. The agent may assemble those facts and recommend the next step, but refund eligibility should come from approved policies and current transaction data. A persuasive answer based on stale information can still be wrong.

APIs and Connectors: The Foundation for Agent Actions
APIs Empowering AI

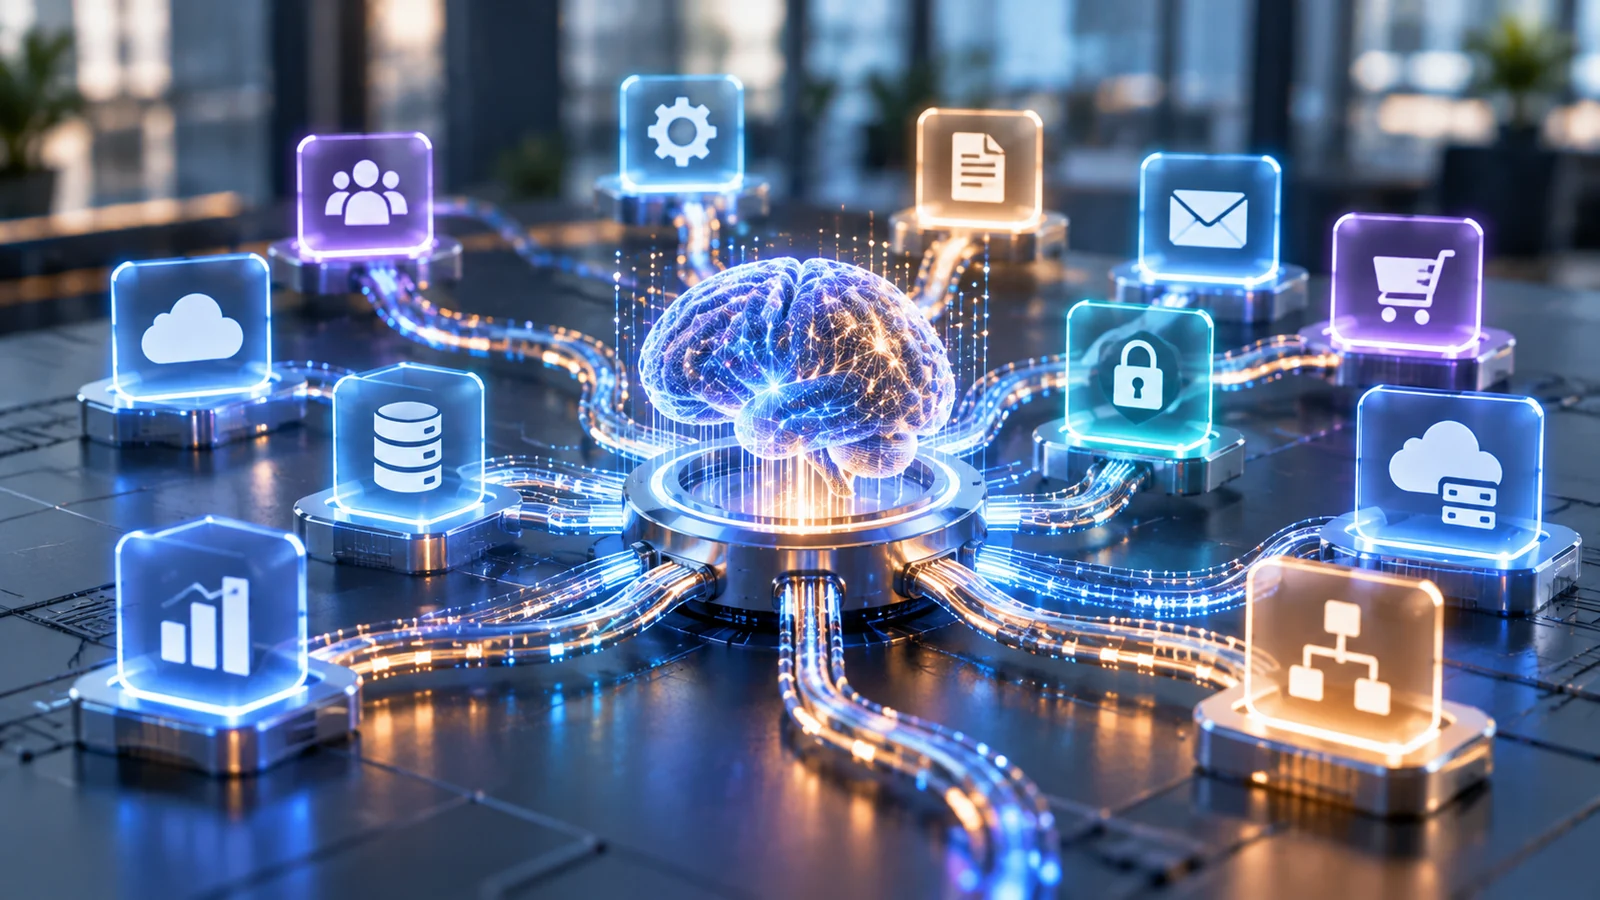
Application programming interfaces allow software to request records or execute defined operations. An enterprise agent typically accesses them through connectors, services, or approved tools rather than obtaining unrestricted database access. Each operation should have a clear purpose, such as retrieving an order, opening a support ticket, or preparing an inventory adjustment.

Read and write operations carry different risks. Reading a customer record may expose confidential information; changing an address, approving a payment, or closing a case affects the business itself. Integrations should validate inputs, honor application permissions, enforce transaction limits, and return explicit success or failure states. A model’s statement that an action succeeded is not a substitute for confirmation from the underlying system.

Reliable connectors must also account for rate limits, network interruptions, duplicate requests, and inconsistent records. For operations that can be retried, developers may need idempotency controls to prevent the same instruction from creating duplicate transactions. Logging should make the sequence of requests and resulting changes auditable.

What Model Context Protocol Adds

Model Context Protocol (MCP) gives AI applications a standard way to discover and use external tools and resources rather than requiring a separate tool interface for every assistant. In a typical arrangement, an MCP client communicates with an MCP server that advertises available functions and exposes structured interfaces. Tool specifications include names and input schemas that an AI application can use to invoke approved operations.

MCP can reduce the need to implement a different tool interface for every model or assistant platform, but it does not eliminate the integrations behind those tools. MCP standardizes how AI applications discover and call available tools, while APIs define how those tools interact with enterprise software. An MCP server may itself call a CRM API, query a knowledge service, or trigger an existing workflow. The enterprise application still controls the authoritative record, and developers remain responsible for authorization and validation.

The MCP specification documents tools, resources, and authorization mechanisms. It also recommends keeping users informed about tool invocations and providing confirmation for consequential actions. Protocol compatibility is not a security certification: an organization must still evaluate each server, its requested permissions, the origin of its data, and the actions it exposes.

Where Retrieval-Augmented Generation Fits

Retrieval-augmented generation helps agents answer questions using relevant information fetched at request time. Instead of relying solely on the model’s trained knowledge, a RAG system retrieves relevant information from approved documents, databases, or other knowledge sources and provides that context to the model when generating a response. This is useful for policy manuals, technical documentation, product information, and internal procedures that change over time.

RAG is not the same as a transaction integration. Retrieving a policy can help determine whether a customer qualifies for an exception; checking whether a refund was actually issued requires an authoritative system query. Documents may explain a process, while APIs reveal current operational state and perform actions. Robust applications often need both.

The quality of RAG depends on document freshness, chunking, retrieval relevance, source attribution, and access controls. Users should not receive confidential passages simply because a search index contains them. Microsoft’s guidance on enterprise knowledge and retrieval emphasizes organization-specific grounding and permission-aware retrieval, while also noting that retrieval has limits and does not guarantee a correct response.

These technologies perform complementary functions within an enterprise AI system. The following comparison summarizes how each contributes to a connected agent workflow.

Technology Primary purpose Role in an AI agent
APIs Expose application operations Retrieve records and perform approved actions
MCP Standardize tool and resource interfaces Discover and invoke structured tools
RAG Retrieve relevant organizational knowledge Ground responses in approved sources
CRM Maintain customer relationship records Provide account and interaction data
ERP Maintain operational records Provide inventory, finance, and fulfillment data

A Practical CRM and ERP Integration Workflow

Imagine a distributor receiving a request to change the delivery date of a major order. The agent first identifies the customer and order through approved CRM and order-management tools. It checks shipment status, inventory allocation, and delivery constraints through ERP or logistics integrations. It then retrieves the applicable service policy through a controlled knowledge search.

If the shipment has not been dispatched and the change falls within documented rules, the agent can prepare an update or propose a permitted action. If changing the delivery date would affect contractual commitments, inventory reservations, or another customer’s allocation, it should stop and route the decision to an authorized employee. After approval, the system should record the change, verify the resulting state, and notify the customer through an approved channel.

The important distinction is between interpreting the request and committing a business transaction. Models may assist with the first; the second requires validated business logic, auditability, and appropriate authorization. For example, an ERP update might succeed even if the subsequent CRM notification fails. The workflow should record the partial completion, confirm the ERP state, and retry or escalate the notification without repeating the original change. That requires reliable state tracking and recovery procedures, especially when services are unavailable or records are edited concurrently.

Designing Security and Governance Into the Connection

Agents should receive the minimum permissions necessary for a specific task. Authentication establishes who a user or system is; authorization determines which records and operations that identity may access. A service agent may be authorized to retrieve order information without receiving permission to modify payment details. A purchasing assistant may draft requests but require managerial approval before committing funds. These boundaries must be enforced by infrastructure and application logic, not only by instructions written in a prompt.

Data retrieved from documents, messages, or external services may contain malicious instructions. Treat that content as untrusted input rather than allowing it to override an agent’s approved role. Limit which tools can be invoked, validate arguments before execution, and separate retrieval from sensitive write operations. Sensitive values should not appear unnecessarily in prompts, logs, or external requests.

The agent also needs an operational owner. Teams should define retention rules, monitor unusual tool usage, maintain a manual fallback, and periodically review credentials and permissions. Salesforce’s guidance on agent actions illustrates why access must be considered at both the end-user and agent-user level, depending on the deployment channel.

Choosing Between Existing Platforms and Custom Integration

Some enterprise platforms already offer supported agent actions, connectors, and knowledge integrations. Those are sensible starting points when their permissions, workflow limits, and vendor support match the requirement. A custom integration becomes more compelling when a business needs specialized rules, legacy-system connectivity, cross-platform orchestration, or independent control over data movement.

Neither approach should be selected only because it is faster to demonstrate. Assess API coverage, licensing implications, identity integration, data residency, logging, recovery procedures, and maintenance obligations. Compare the entire operational workflow rather than the quality of a model’s response in isolation.

Before committing to an integration approach, organizations should assess the technical and operational requirements that determine long-term reliability.

Readiness area Key question
Data quality Are authoritative records accurate and available?
API capabilities Do integrations support required operations?
Access controls Are permissions scoped to each user and agent?
Security Are sensitive data and write actions protected?
Reliability Can retries and partial failures be reconciled?
Monitoring Can decisions and tool activity be traced?
Maintenance Who owns updates, testing, and support?

Testing the Complete Workflow

A useful pilot should include ordinary requests, missing documents, contradictory records, expired credentials, denied permissions, API timeouts, repeated instructions, and cases that require approval. Test whether the agent retrieves the correct evidence, chooses the right tool, respects authorization boundaries, and accurately reports what did or did not happen.

Measure successful end-to-end completion, error and escalation rates, latency, correction effort, and cost per resolved task. Evaluate the final state in CRM or ERP, not merely the generated message. A response can sound correct even when the record was not updated or an operation failed halfway through.

Enterprise agent integration succeeds when the model’s flexible interpretation is combined with dependable data retrieval and controlled application behavior. MCP can standardize tool access, RAG can provide grounded organizational context, and CRM or ERP APIs can expose operational state. The lasting value comes from engineering those pieces into a secure, testable workflow that employees can trust and correct.

Related reading: Which AI Software Is Right for Your Business? An In-Depth Look
AI in Software Development: Planning to Production

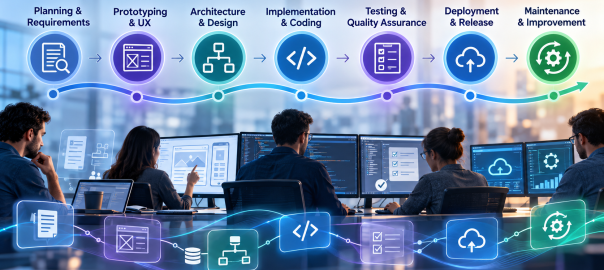
AI-assisted development is often reduced to code generation. Its more consequential effect is how engineering teams move information and decisions through the entire software development lifecycle (SDLC). Requirements become test cases, prototypes inform architecture, code changes trigger reviews, and operational feedback shapes the next release. AI can assist at every handoff—but only when teams retain clear ownership of the decisions.

Google’s 2025 DORA research describes AI as an amplifier of organizational strengths and weaknesses. That is a useful lens: accelerating one stage of development does not automatically produce better software or faster, safer releases. The opportunity lies in connecting AI-assisted work to a disciplined delivery process.

1. Discovery and Requirements: Turning Ambiguity into a Plan

Software projects routinely begin with incomplete requests, competing priorities, and undocumented assumptions. AI can help analyze stakeholder notes, summarize interviews, group feature requests, draft user stories, and identify requirements that need clarification. For an existing application, it may also help teams understand documentation and trace likely dependencies.

The meaningful deliverable is not a polished requirements document produced in seconds. It is a set of decisions that stakeholders can validate: intended users, acceptance criteria, business rules, integrations, accessibility needs, and constraints. Have product owners confirm those decisions before they become implementation instructions.

2. Prototyping and UX: Exploring Alternatives Earlier

UX Design

AI can accelerate early experiments by generating interface concepts, sample content, interaction flows, and disposable prototypes. That shortens the distance between a verbal idea and something stakeholders can inspect. It also makes comparing multiple approaches less expensive than committing immediately to one design.

A prototype, however, does not establish production readiness. Generated interfaces still need research with actual users, accessibility checks, responsive behavior, and validation against real workflows. Teams should label experimental code clearly so a quick demonstration is not silently promoted into a maintained product.

3. Architecture and Technical Planning: Testing the Design Before Building

AI assistants can help engineers compare architecture options, outline service boundaries, document API contracts, surface migration questions, and explore the operational implications of a design. Used effectively, AI-assisted planning can reveal architectural trade-offs earlier in the development process: centralized versus distributed components, managed services versus custom infrastructure, or synchronous versus event-driven integrations.

The architect still needs to evaluate scalability, security boundaries, data ownership, cost, maintainability, and team expertise. A convincing AI-generated diagram cannot verify that an architecture fits a company’s legacy systems. Treat the output as a set of alternatives and questions for technical review, not an approval authority.

4. Implementation: Coding With Context and Constraints

In development environments, AI can suggest functions, explain unfamiliar code, generate boilerplate, propose refactors, and help developers navigate large repositories. Agentic tools can sometimes work across multiple files and prepare changes for review. GitHub documents AI assistance across planning, coding, review, testing, and shipping workflows, illustrating that the tool’s role now extends beyond autocomplete.

Coding assistants are more useful when teams maintain clear project documentation, repository-specific instructions, consistent coding standards, and reliable automated tests. Ask for small, reviewable changes linked to approved requirements and verify them against existing interfaces. Keep the connection between requirements, implementation changes, and corresponding tests traceable throughout review. Keep changes in version control, inspect dependencies, and apply the same engineering standards regardless of who—or what—drafted the code.

5. Testing and Quality Assurance: Expanding Coverage, Not Lowering Standards

AI can propose unit tests, identify untested paths, generate representative test data, and help translate acceptance criteria into automated checks. During review, it can flag suspicious changes or explain why a failure may have occurred. GitHub’s Copilot documentation, for example, describes AI-generated pull-request review suggestions.

But test generation is not the same as test adequacy. A system may generate tests that merely confirm its own incorrect assumptions. Engineers still need independent expectations, meaningful integration tests, security scanning, performance testing, and human judgment for high-risk functionality. The strongest workflow uses AI to broaden the search for defects while maintaining objective pass/fail gates.

6. Deployment and Release: Connecting Changes to Operational Evidence

AI can assist with deployment manifests, infrastructure templates, release notes, runbook drafts, and explanations of failing CI/CD pipelines. It can also summarize changes across pull requests so release managers understand what is moving into production.

Production changes should still pass controlled build pipelines, automated checks, approval gates, and rollback planning. Credentials and infrastructure access require explicit limits. An AI assistant may recommend a deployment action; that is different from granting it unrestricted authority to execute one. Rehearsing failures and validating recovery paths are more valuable than accelerating a release that cannot be safely reversed.

7. Maintenance and Modernization: Learning From Software in Use

After launch, AI can help triage incident reports, cluster recurring support issues, summarize logs, locate likely fault paths, and draft documentation. It can also support legacy modernization by explaining old components, mapping dependencies, and suggesting incremental refactors.

Here, context quality matters especially. A diagnosis based on incomplete telemetry or outdated documentation may send developers in the wrong direction. Correlate AI suggestions with observability data, reproducible defects, and actual user impact. Prefer incremental changes supported by regression tests over wholesale rewrites generated from partial understanding.

An End-to-End Example: Developing an Enterprise Customer Portal

AI Enterprise Workflow

The value of AI across the SDLC becomes clearer when these applications are considered as parts of a single project. Consider a team building a customer portal that connects to an existing enterprise platform. During discovery, AI can organize stakeholder interviews into candidate requirements and flag unclear acceptance criteria. Designers can use the approved requirements to explore interface concepts while engineers assess authentication, data access, and integration choices. Coding assistants can then help implement small, reviewable features and suggest tests tied to the requirements. After release, AI can help analyze support tickets and performance logs to identify improvements for later iterations. Product owners, designers, engineers, and release managers remain accountable for validating outputs and approving decisions throughout.

SDLC stage AI assistance Human responsibility
Discovery Requirements analysis, user stories Validate business requirements
Prototyping and UX Interface ideas and prototypes Test usability and accessibility
Architecture Compare designs and integrations Approve technical decisions
Implementation Code suggestions and refactoring Review code and dependencies
Testing Test ideas and defect analysis Verify coverage and quality
Deployment Release notes and CI/CD support Authorize and monitor release
Maintenance Incident triage and legacy analysis Validate fixes and improvements

Making AI Useful Across the Entire Lifecycle

A fragmented rollout can make one developer faster while creating more downstream review, integration, and maintenance work. A feature drafted in half the usual time can still slow delivery if it introduces defects, requires extensive review, or breaks an integration. DORA’s 2025 findings emphasize that gains depend on the surrounding organizational system, including strong engineering practices and feedback loops. Measure dependable software delivery, not simply the quantity of generated code.

Start with a few high-friction tasks, such as requirements clarification, test design, or incident triage. Establish approved tools, repository access rules, review responsibilities, and quality gates. Then measure end-to-end results: lead time, rework, escaped defects, deployment stability, and time spent on meaningful engineering work. Compare those results with a baseline rather than relying only on self-reported productivity.

The most durable use of AI is as a continuous engineering assistant, not a replacement for product judgment or technical accountability. The greatest value comes from connecting AI-assisted planning, development, testing, and operations into a reliable, continuously improving software delivery process.

Mystic Media is a Summer 2026 Clutch Global Award Winner!

We’re proud to announce that Mystic Media has been named a Summer 2026 Clutch Global Award winner for API Development, placing us among the top 15 providers worldwide in our category on Clutch. This recognition reflects the quality of the solutions we build and the trust our clients place in us.

What are the Clutch Global Awards?

Clutch powers how businesses discover, evaluate, and hire the right B2B service partners. The Clutch Global Awards honor the very best firms based on verified client reviews, market presence, and demonstrated expertise. This summer, only the top 15 companies in each IT and development category earned this distinction, making it one of the most selective recognitions in the industry.

“The pace of innovation in IT and software development continues to accelerate, and these firms are setting the standard through the results they deliver for clients,” said Mike Beares, Founder and CEO of Clutch. “A Clutch Global Award is earned through exceptional service and the voices of real customers.”

Built on Real Client Feedback

The Clutch Global Awards are rooted in verified client reviews, not self-nominations or popularity. This recognition reflects the confidence our clients place in us and the outcomes we achieve together. Every review on our Clutch profile represents a genuine partnership and a successful engagement.

Mystic Media is an AI‑accelerated software partner for teams that need to move fast without compromising reliability. We combine human expertise with modern tooling, code copilots, automated testing, CI/CD, and observability, to double throughput on scoped tasks while maintaining review gates and security.

Thank you to our team and our clients for making this achievement possible. Our success is built on your trust, collaboration, and shared commitment to excellence.

“Receiving this Clutch Award is a meaningful recognition of our team’s commitment to delivering exceptional results and building lasting client partnerships. We’re grateful to our clients for their trust and feedback, and we look forward to continuing to help them succeed.”

Ready to Partner with an Award-Winning Team?

Visit our Clutch profile to read client reviews, or contact us to discuss your next project.

AI Token Optimization: A Developer’s Guide to Faster, Smarter, Cost-Efficient AI Software

AI Tokenization

AI tokens are one of the most important concepts to understand when adding AI to a software project.

At a simple level, a token is a small piece of text that an AI model reads or writes. A token might be a full word, part of a word, a number, a punctuation mark, or even a symbol. When you send a prompt to an AI model, that prompt is broken into tokens. When the model responds, the answer is also generated as tokens.

Why does this matter?

Because tokens affect cost, speed, accuracy, and scalability.

Every request you send to an AI model has an input cost and an output cost. The more text you send, the more tokens you use. The longer the model’s response, the more tokens it generates. In small experiments, this may not feel important. But in a real software project, where an application may process thousands of requests per day, inefficient token usage can quickly become expensive.

Tokens also affect performance. Larger prompts take longer to process. Longer responses take longer to generate. If your application depends on AI to power chat, search, support, document analysis, workflow automation, or internal tooling, slow responses can create a poor user experience.

Most importantly, tokens affect the quality of the result. Sending more information does not always lead to a better answer. In many cases, sending too much information gives the model more room to misunderstand the task, focus on the wrong details, or produce inconsistent output.

Good AI engineering is not about giving the model everything. It is about giving the model the right information at the right time.

Token Optimization Is a Software Architecture Problem

Token optimization is often treated like a prompt-writing problem. That is part of it, but it is not the whole story.

In a production software system, token usage is shaped by architecture. It depends on how you store data, retrieve context, format prompts, handle memory, manage user history, structure model responses, and decide when AI should be used at all.

A developer should think about tokens the same way they think about database queries, API calls, caching, logging, and background jobs. Token usage is a resource. If it is unmanaged, it can become a bottleneck.

For example, imagine a customer support application that uses AI to respond to incoming messages. A simple implementation might send the full customer history, every previous ticket, all available product documentation, and the current message into the prompt.

That may work in a demo.

But in production, it is wasteful. Most of that information will not be relevant to the current request. The model may spend tokens processing old tickets, outdated policies, or duplicate data. The response may become slower, more expensive, and less accurate.

A better approach is to retrieve only the most relevant customer details, include a short summary of recent interactions, pull a few matching documentation sections, and give the model a clear instruction for the task.

That is token optimization in practice.

Better Context, Not More Context

One of the biggest mistakes teams make is assuming that more context always improves AI output.

It does not.

AI models work best when the prompt is focused. If the task is to summarize a contract clause, the model probably does not need the entire contract history, every email about the contract, and the company’s full legal playbook. It needs the relevant clause, the business objective, any rules that apply, and the desired output format.

The goal is not to minimize context blindly. The goal is to maximize useful context.

This distinction matters. If you remove too much information, the model may not have enough to produce a good answer. If you include too much, the model may get distracted. Effective token optimization sits between those two extremes.

Developers can improve context quality by filtering unnecessary fields, removing duplicates, summarizing older content, trimming irrelevant metadata, and using retrieval systems to select the most relevant documents.

For example, instead of passing an entire database object into a prompt, pass only the fields the model needs. Instead of sending a full chat transcript, pass the current user question and a concise summary of prior context. Instead of including every document in a knowledge base, use search or embeddings to retrieve the few sections most likely to answer the user’s question.

The model should not have to search through a messy prompt. Your application should do that work first.

Treat Prompts Like Software Interfaces

Optimize AI Tokens

A production prompt should not be treated like a casual message. It should be treated like an interface.

When developers design an API, they think about inputs, outputs, validation, edge cases, and error handling. Prompts deserve the same discipline.

A strong prompt usually includes a clear role, a specific task, relevant context, business rules, and a defined output format. It avoids unnecessary repetition. It separates instructions from user data. It tells the model exactly what to do when information is missing.

This structure reduces wasted tokens and improves reliability.

For example, a vague prompt might say:

“Look at this customer message and help them.”

A better prompt would say:

“You are a customer support assistant. Classify the customer’s issue, identify the likely product area, and draft a concise response. Use only the provided policy information. If the answer is not available, say that the issue should be escalated.”

The second version is more useful because it gives the model boundaries. It reduces guesswork. It also creates a response that is easier for the application to parse and use.

Formatting matters too. Labeled sections, compact JSON, bullet points, and consistent field names can help the model understand the prompt more efficiently. This does not mean every prompt needs to be rigid or overly engineered, but structure usually improves both token efficiency and output quality.

Summarization Is a Key Optimization Tool

Many AI applications need memory. A user may have a long conversation with a chatbot. A project management assistant may need to understand weeks of updates. A sales assistant may need context from multiple emails, meetings, and CRM notes.

The simple solution is to keep sending everything.

The better solution is summarization.

Summaries allow your system to preserve important information while reducing token usage. Instead of storing and resending an entire conversation, you can maintain a running summary that captures user preferences, decisions, unresolved questions, and important facts.

This is especially useful when conversations become long. Older messages may still matter, but they rarely need to be included word for word. A well-designed summary can preserve the important context in a fraction of the tokens.

There are a few important rules for summarization. First, summaries should be updated carefully. If the summary loses important details, the model’s future responses may degrade. Second, summaries should distinguish between facts, assumptions, and open questions. Third, summaries should be structured enough for the application to use.

For example, a project assistant might maintain a summary with sections for goals, stakeholders, deadlines, decisions, blockers, and next steps. This is far more efficient than replaying every message in the project history.

Retrieval Beats Bulk Prompting

When an application needs external knowledge, retrieval is usually better than bulk prompting.

Instead of stuffing large documents into the prompt, use a retrieval system to find the most relevant sections. This approach is commonly used in retrieval-augmented generation, or RAG.

The idea is straightforward. Documents are split into chunks. Those chunks are indexed. When a user asks a question, the system searches for relevant chunks and sends only the best matches to the model.

This reduces token usage and improves answer quality. The model receives focused context instead of a large pile of loosely related information.

However, retrieval must be designed carefully. Chunk size matters. If chunks are too small, they may lose context. If they are too large, they may waste tokens. Ranking matters too. If the retrieval system sends irrelevant chunks, the model will still struggle.

In practice, good retrieval often requires testing. Developers should evaluate whether the right documents are being selected, whether the chunks contain enough surrounding context, and whether the model can cite or explain where its answer came from.

RAG is not just a cost-saving technique. It is a reliability technique.

Optimize the Output

Optimize AI OutputInput tokens get most of the attention, but output tokens matter too.

If your system asks the model to write long responses when short ones would work, you are wasting tokens. You may also be making the product harder to use.

For internal workflows, structured outputs are often better than paragraphs. If the task is classification, routing, extraction, scoring, or validation, the model should return a predictable format. JSON is often useful because it can be parsed directly by the application.

For user-facing features, response length should match the experience. A technical support chatbot may need a short answer with steps. A document analysis tool may need a detailed explanation. A notification system may only need one sentence.

Developers should be intentional about this. Define the desired response length. Specify the format. Ask the model not to include unnecessary explanation when the application only needs a value.

For example, if the model is deciding whether a support ticket should be escalated, the response does not need a full essay. It may only need:

  • escalation_required: true
  • reason: “Customer reports data loss”
  • priority: “high”

That is cheaper, faster, and easier to use.

Cache What You Can

Not every AI request needs to be generated from scratch.

If your application repeatedly asks the same or similar questions, caching can reduce token usage significantly. Common examples include product descriptions, policy explanations, generated summaries, classification results, and document extractions.

Caching is especially useful when the input data does not change often. If a model has already summarized a document, store that summary. If it has already classified a support category, store the classification. If a user asks a common question, reuse a verified answer when appropriate.

Of course, caching must be handled carefully. Stale AI output can create problems. Your system should know when source data has changed and when cached responses should expire.

Still, for many software projects, caching is one of the simplest ways to reduce cost and improve speed.

Use the Right Model for the Task

Token optimization is not only about reducing token count. It is also about using the right model.

Not every task requires the largest or most expensive model available. Simple classification, formatting, extraction, and rewriting tasks can often be handled by smaller or faster models. More complex reasoning, code analysis, planning, or high-stakes decision support may require a stronger model.

A thoughtful AI architecture may use multiple models. A lightweight model can classify intent. A retrieval system can gather context. A stronger model can handle the final response only when needed.

This kind of routing can make an application more efficient without sacrificing quality.

The key is measurement. Developers should test model performance against real examples. If a smaller model performs well enough for a task, it may be the better production choice. If it fails on edge cases, the cost savings may not be worth it.

Measure Token Usage Early

Measure Token Usage Early

Teams should measure token usage from the beginning of a project, not after the bill becomes a problem.

Track average input tokens, average output tokens, cost per request, latency, error rates, and output quality. Look for outliers. A few unusually large prompts may account for a significant portion of total cost.

Logging is important here. Developers should be able to inspect what context was sent, what the model returned, and how many tokens were used. This makes it easier to debug both cost and quality issues.

Token optimization should be part of the development cycle. Build, measure, adjust, and repeat.

Final Thoughts

AI can add significant value to a software project, but it needs to be engineered with discipline. Token optimization is a major part of that discipline.

The goal is not to make prompts as short as possible. The goal is to make every token useful.

Send the model the right context. Structure prompts clearly. Summarize long histories. Retrieve relevant knowledge instead of bulk-loading documents. Limit output when appropriate. Cache repeatable work. Choose the right model for each task. Measure everything.

When developers approach AI this way, they build systems that are faster, more affordable, and more reliable.

That is the difference between an AI demo and an AI-powered product that is ready for real users.